OCR for the documents that are harder to read.
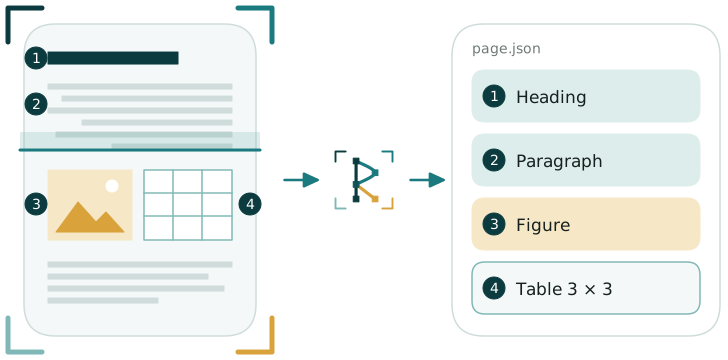
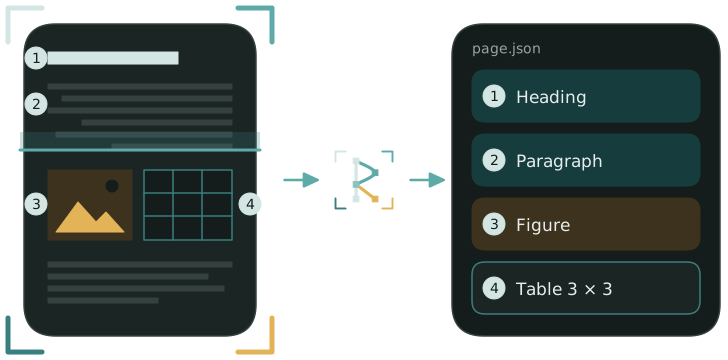
Runemic builds OCR models and tools for pages that standard OCR often gets wrong: non-Latin scripts, old scans, handwriting and complicated layouts. You get the text back in reading order, with headings, lists and tables kept.
Live 5 free pages a day without an account; $5 of free credit when you sign in.
Receipts, letters, books, forms and archives.


Rune-1 models
Multilingual OCR for difficult documents. Reads the text, the layout and the basic structure of a page, across many scripts and languages.
Model card

Runemic Scan
Scan a bill, receipt or letter with your phone. Runemic reads it and pulls out the useful information.
Products

Digitization
We digitize collections of books, letters and other documents: we scan them, run OCR and return searchable files and structured data.
ServicesTry it free
Read up to 5 pages a day in your browser, with no account. When you want more, sign in with GitHub or Hugging Face.
- 5 free pages a day at runemic.com/try, no sign-up
- Sign in for $5 of free credit, no card needed
- Compare up to three models, and get an API key with cURL, Python and JavaScript examples
# one page in, Markdown out
curl https://api.runemic.com/v1/ocr \
  -H "Authorization: Bearer $RUNEMIC_KEY" \
  -F "file=@page.png"

# → { "text": "# Invoice No. 4821 …",
    "usage": { "cost_usd": 0.002 } }