Best OCR for Persian, tested
Runemic preview: Gemma 4 26B made the fewest mistakes on 8 Persian test pages: 3.1% of characters wrong. Results for 6 OCR engines, on the versions listed below.
Made by Runemic Runemic's own models are in this test. The pages, the scoring code and every engine's output are public, so you can check it.
| # | OCR engine | Runs on | Character errors | Word errors | Failed pages |
|---|---|---|---|---|---|
| 1 | Runemic preview: Gemma 4 26B Runemic (hosted model) · preview-gemma-4 |
API | 3.1% | 4.9% | – |
| 2 | EasyOCR Jaided AI · 1.7.2 |
CPU or GPU | 7.2% | 42.6% | – |
| 3 | Runemic preview: Llama 4 Scout Runemic (hosted model) · preview-llama-4-scout |
API | 7.7% | 9.9% | – |
| 4 | PaddleOCR Baidu PaddlePaddle · 3.7.0 |
CPU or GPU | 9.6% | 26.6% | – |
| 5 | Tesseract open source (originally Google) · 5.3.4 |
CPU | 17.9% | 28.6% | – |
| 6 | Runemic preview: Mistral Small 3.1 Runemic (hosted model) · preview-mistral-small |
API | 18.5% | 31.6% | – |
Lower is better. Character error rate: the share of characters the engine got wrong, left out or added, compared with the correct text. Averaged over the 8 pages.
Character errors on each Persian test page
| OCR engine | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 |
|---|---|---|---|---|---|---|---|---|
| Runemic preview: Gemma 4 26B | 0.0% | 0.0% | 24.7% | 0.0% | 0.0% | 0.0% | 0.0% | 0.0% |
| EasyOCR | 1.3% | 1.8% | 9.8% | 16.1% | 2.1% | 13.8% | 11.0% | 1.9% |
| Runemic preview: Llama 4 Scout | 0.0% | 1.1% | 58.7% | 0.0% | 0.5% | 0.0% | 1.2% | 0.0% |
| PaddleOCR | 0.0% | 1.1% | 47.7% | 16.8% | 2.7% | 2.7% | 5.2% | 1.0% |
| Tesseract | 3.4% | 1.4% | 43.8% | 53.1% | 7.0% | 22.8% | 7.5% | 3.9% |
| Runemic preview: Mistral Small 3.1 | 0.4% | 48.0% | 54.0% | 40.6% | 0.0% | 0.0% | 5.2% | 0.0% |
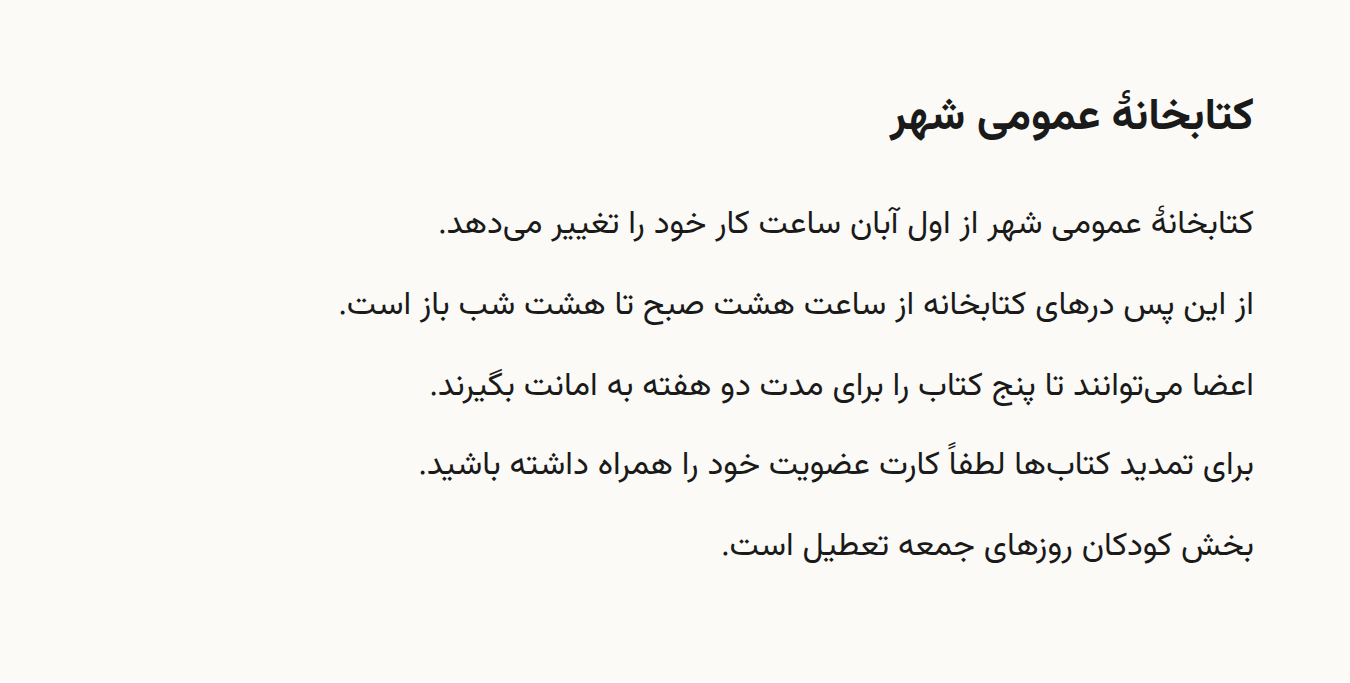
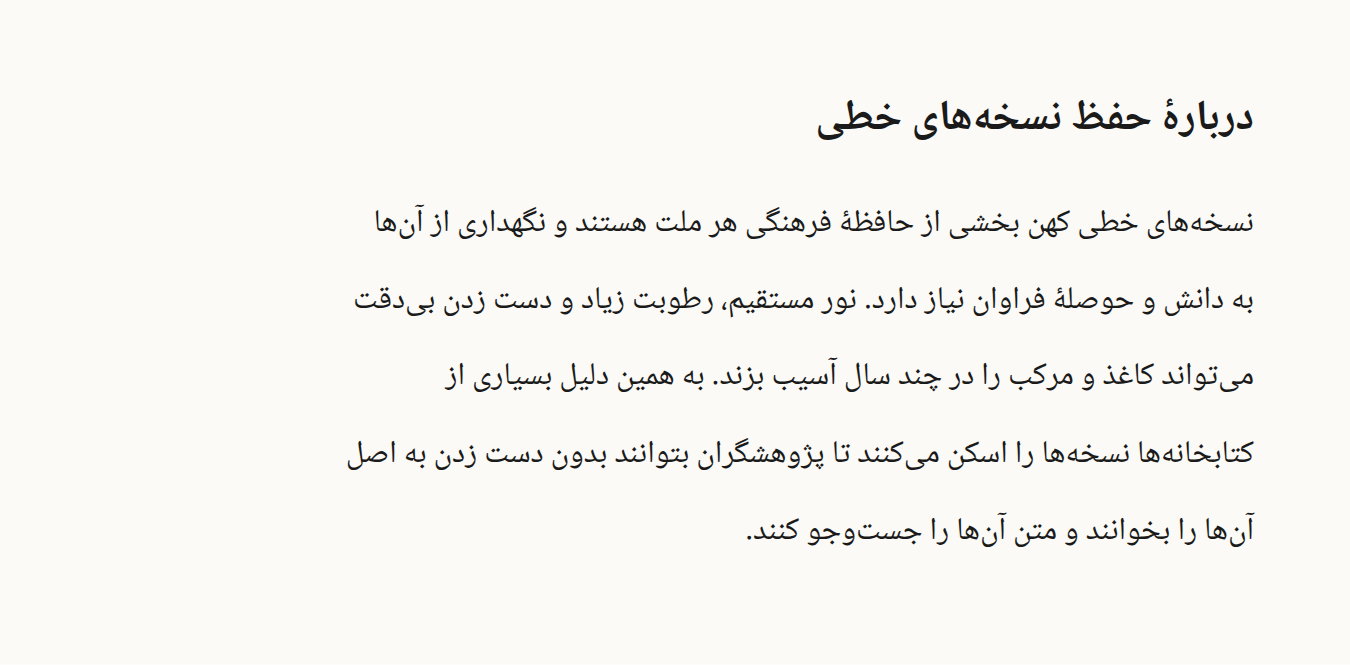
- 1 Modern prose, clean, Vazirmatn
- 2 Modern prose, Noto Naskh (book font)
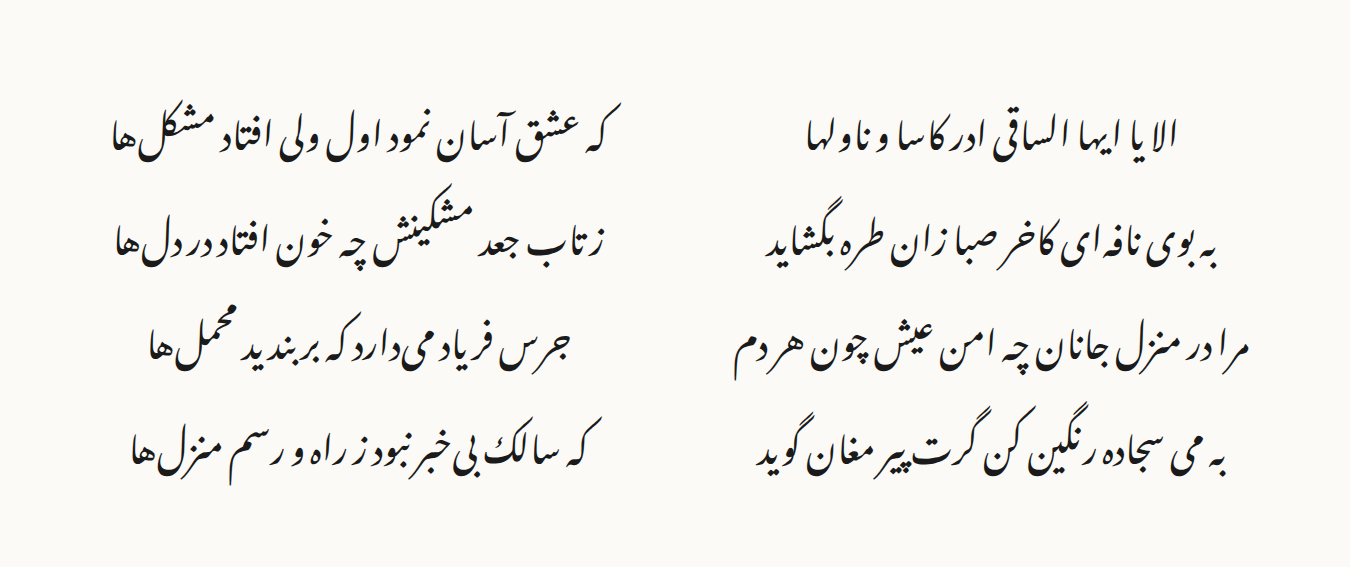
- 3 Poetry in Nastaliq (Hafez, ghazal 1)
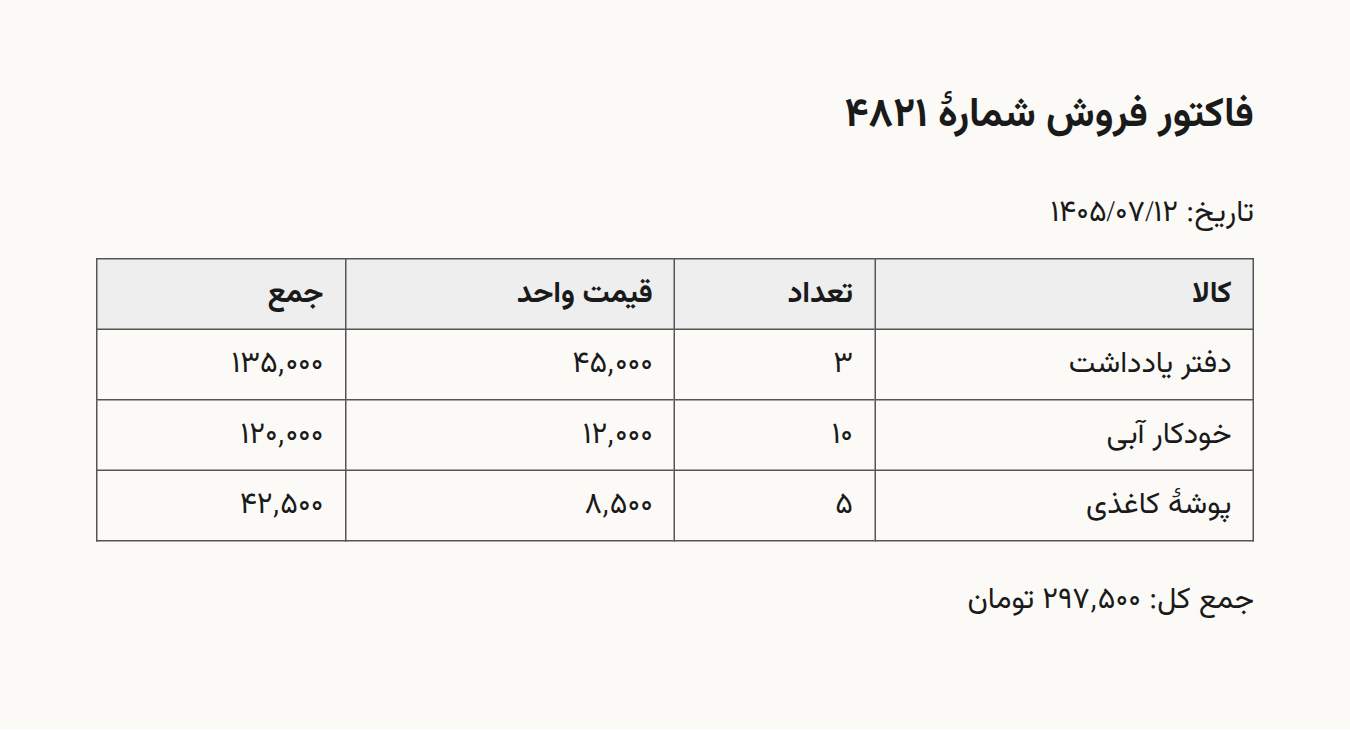
- 4 Table with Persian digits
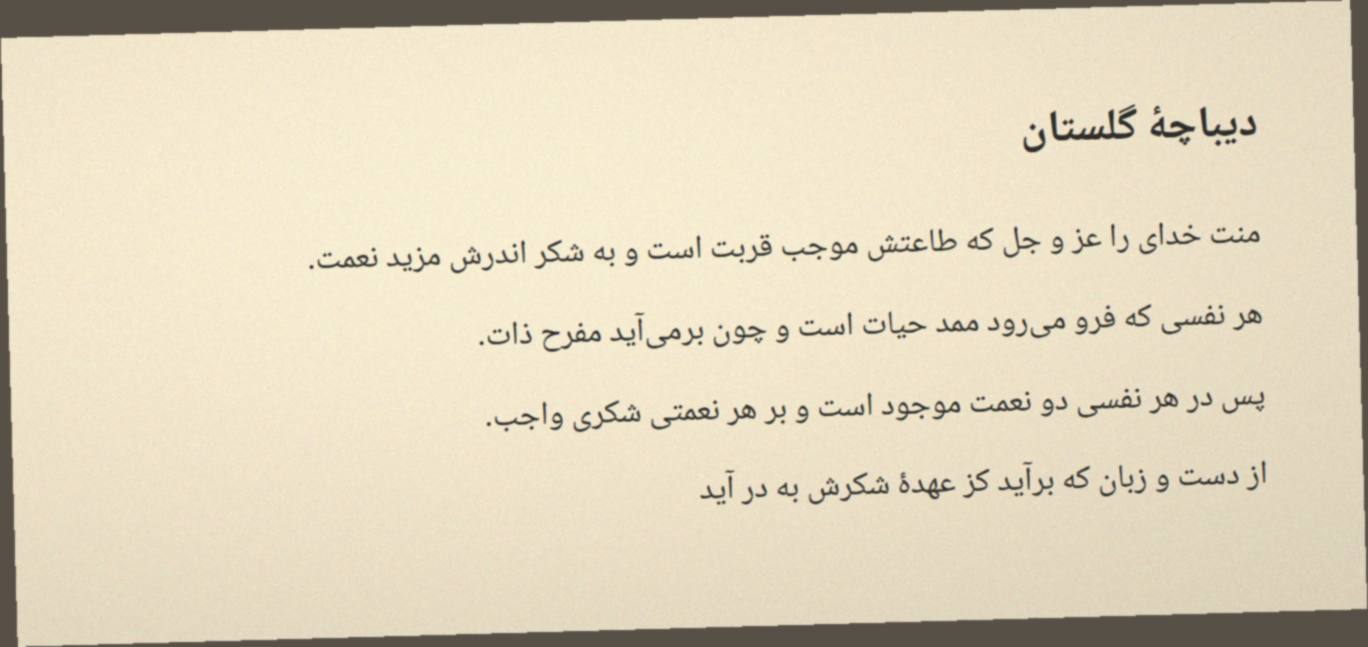
- 5 Classical prose, photographed (Saadi, Golestan)
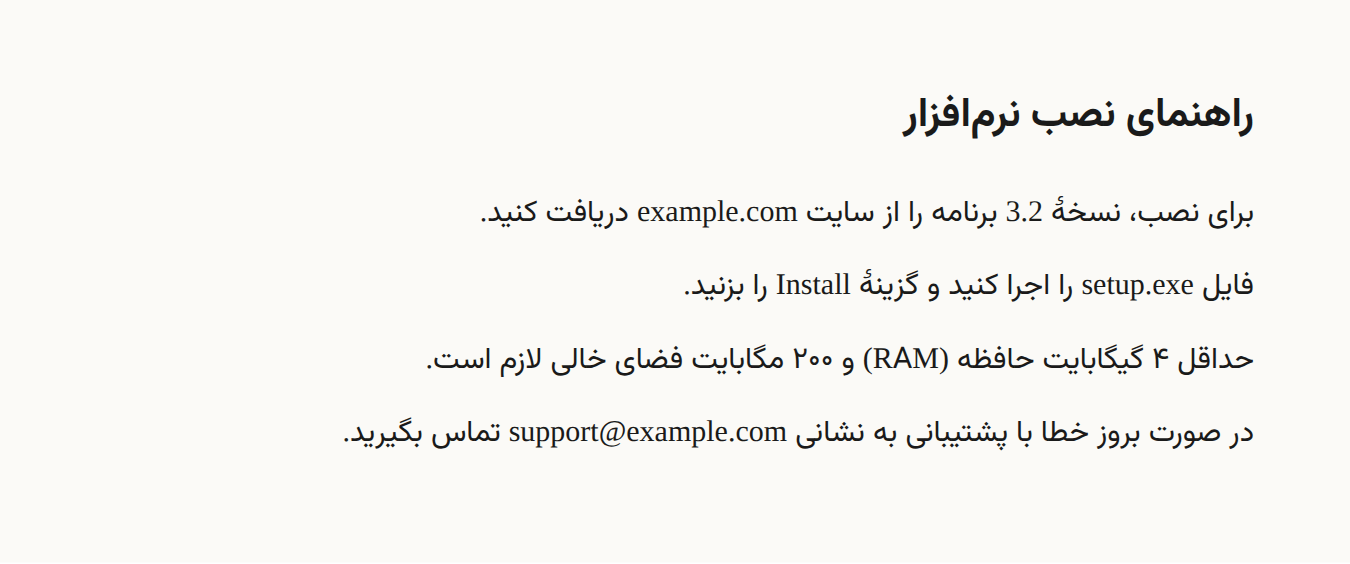
- 6 Persian mixed with English and numbers
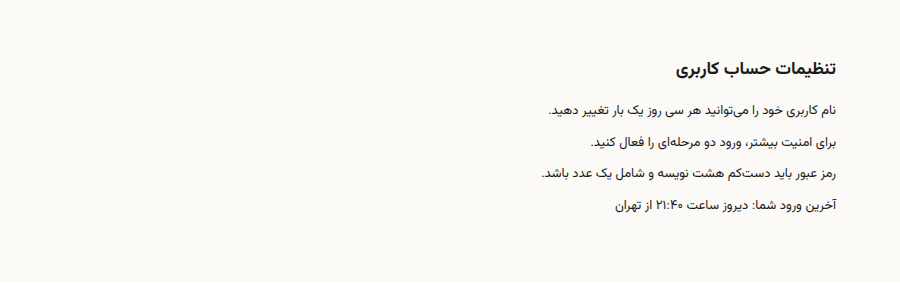
- 7 Small text, screenshot-like (13 px)
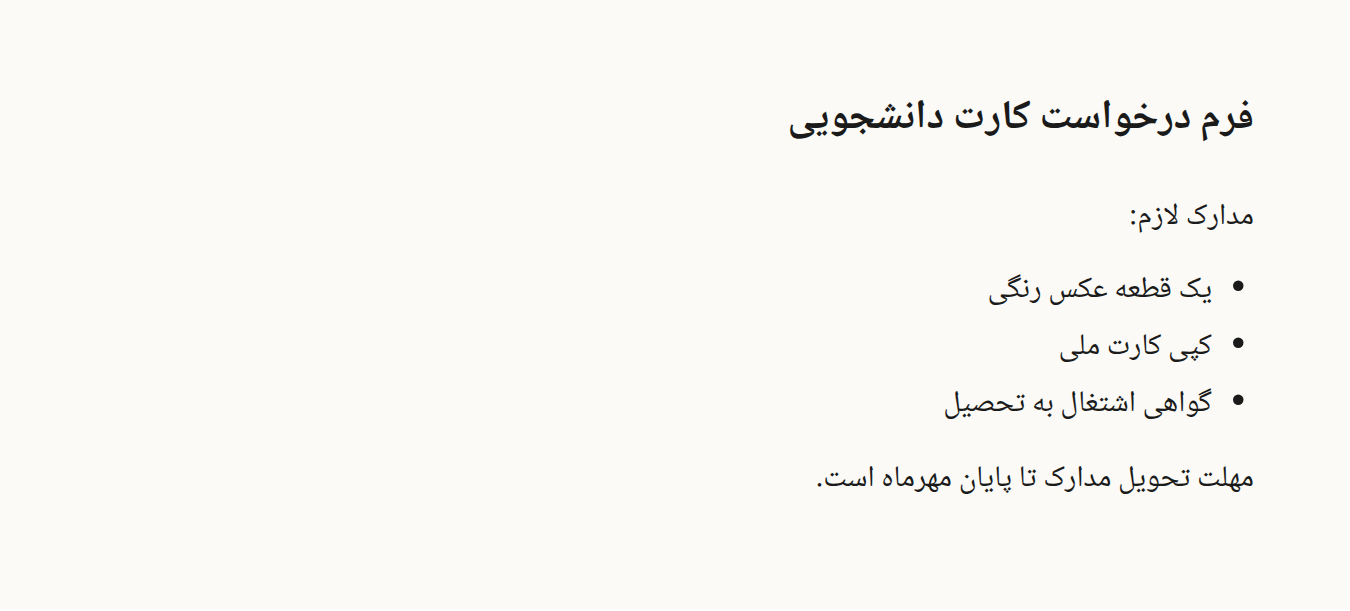
- 8 Form with headings and a list
The 8 Persian test pages
Each page was rendered from text we know, so every mistake can be counted exactly. The classical texts are public domain (Hafez, Saadi); the modern texts were written for this test.
How the Persian OCR test works
- Every engine reads the same 8 images with its default settings, as its makers ship it.
- Before scoring, all output is normalised the same way: Arabic and Persian forms of ی and ک, digits, short vowels and Markdown marks don't count as errors. Character errors leave out spaces and the zero-width non-joiner, which Persian writers use inconsistently; word errors count them.
- Runemic's preview models are called through the public API, like any customer would.
- Not tested yet: Google Cloud Vision, ABBYY FineReader, Adobe Acrobat and Mistral OCR (paid services). GLM-OCR and LightOnOCR don't list Persian as a language.